|
|
Latest Articles

New Movies


Foreign




|
Torrent Description
Обучающие видео » Видеоуроки и обучающие интерактивные DVD » Продажи, бизнес
Using R for Big Data with Spark [hr] Год выпуска: 2016 Производитель: O'Reilly Media Сайт производителя: shop.oreilly.com/product/0636920056621.do Продолжительность: 02:20:02 Тип раздаваемого материала: Видеоурок Язык: Английский [hr] Описание: Аналитики, знакомые с данными R научитесь использовать мощь Спарк, распределенных вычислений и облако хранения в этом курсе, который показывает вам, как использовать свои навыки R в большой среде данных. [hr] Data analysts familiar with R will learn to leverage the power of Spark, distributed computing and cloud storage in this course that shows you how to use your R skills in a big data environment. You'll learn to create Spark clusters on the Amazon Web Services (AWS) platform; perform cluster based data modeling using Gaussian generalized linear models, binomial generalized linear models, Naive Bayes, and K-means modeling; access data from S3 Spark DataFrames and other formats like CSV, Json, and HDFS; and do cluster based data manipulation operations with tools like SparkR and SparkSQL. By course end, you'll be capable of working with massive data sets not possible on a single computer. This hands-on class requires each learner to set-up their own extremely low-cost, easily terminated AWS account. Discover how to use your R skills in a big data distributed cloud computing cluster environment Gain hands-on experience setting up Spark clusters on Amazon's AWS cloud services platform Understand how to control a cloud instance on AWS using SSH or PuTTY Explore basic distributed modeling techniques like GLM, Naive Bayes, and K-means Learn to do cloud based data manipulation and processing using SparkR and SparkSQL Understand how to access data from the CSV, Json, HDFS, and S3 formats Manuel Amunategui is a data science practitioner, consultant, teacher, and author with 16+ years of data science experience. A former quantitative analyst for a Wall Street brokerage firm, he now serves as the lead data scientist for Providence Health & Services in Portland, Oregon. In his free time, Manuel does competitive data modeling on Kaggle.com, CrowdANALYTIX.com, Datascience.net, and DrivenData.org. [spoiler="Содержание"] Introduction Welcome to the Course 04m 21s About the Author 01m 08s How To Access Your Working Files 01m 15s Creating Clusters on Amazon Web Services Creating an AWS Launching Instance 09m 39s Connecting to AWS Instance using SSH 06m 18s Connecting to AWS Instance using PuTTY 08m 37s Starting Spark Clusters Part 1 09m 01s Starting Spark Clusters Part 2 09m 55s Terminate Your Clusters 00m 58s Data and Modeling Basics Data Basics 08m 33s Modeling with Gaussian Generalized Linear Models 11m 19s Modeling with Binomial Generalized Linear Models 09m 33s Naive Bayes and K-Means Modeling 09m 14s Data Sources and Data Manipulation Bigger Data and S3 07m 27s Accessing S3 Spark Dataframes 04m 57s SparkR Dataframe Operations 11m 01s SparkSQL 05m 16s Various Brief Look at HDFS 10m 59s Brief Look at Databricks Community Edition 08m 19s Conclusion Wrap Up and Thank You 02m 02s [/spoiler] Файлы примеров: отсутствуют Формат видео: MP4 Видео : AVC, 1280x720 (16:9), 29.970 (29970/1000) fps, ~631 Kbps avg, 0.023 bit/pixel Аудио: 44.1 KHz, AAC LC, 2 ch, ~128 Kbps [spoiler="Скриншоты"] 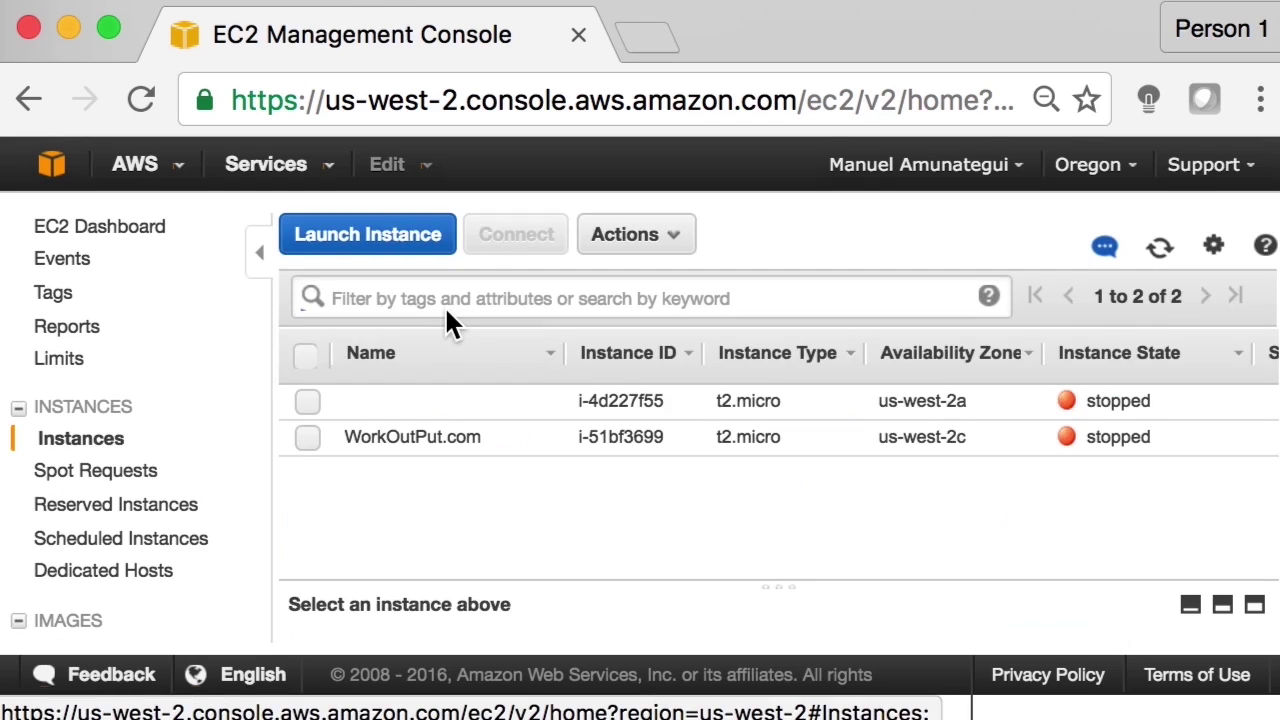 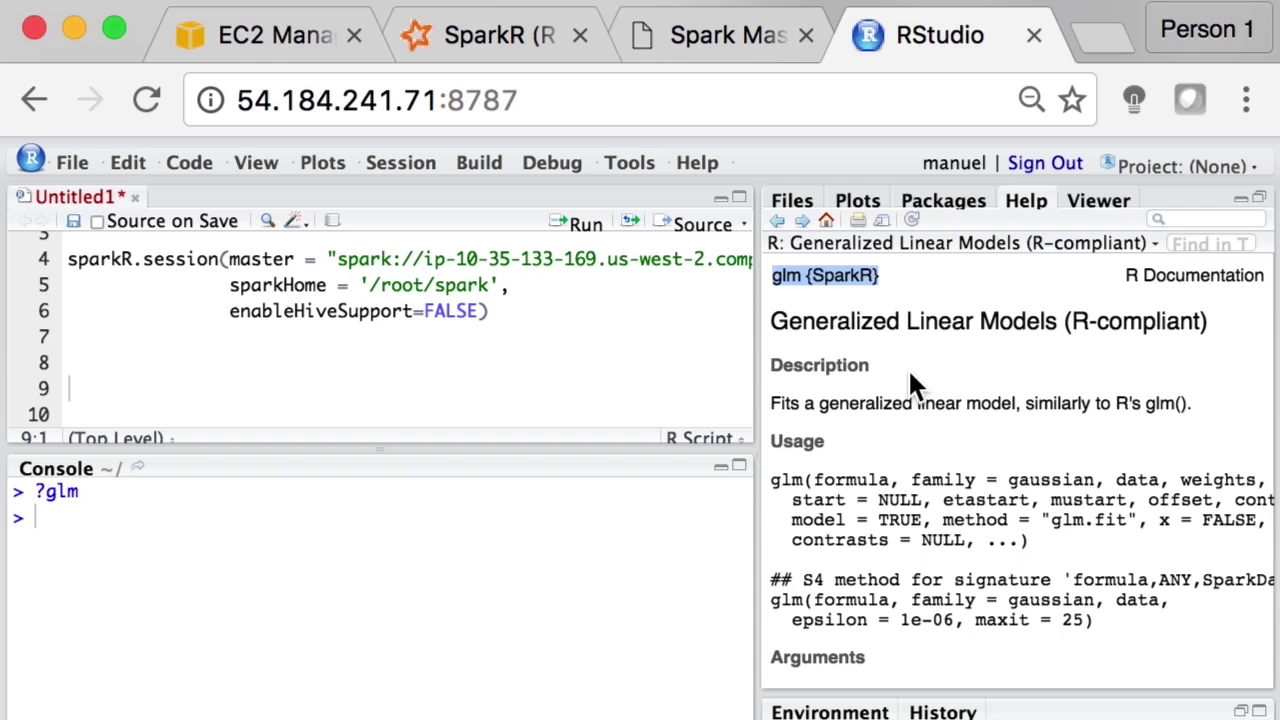  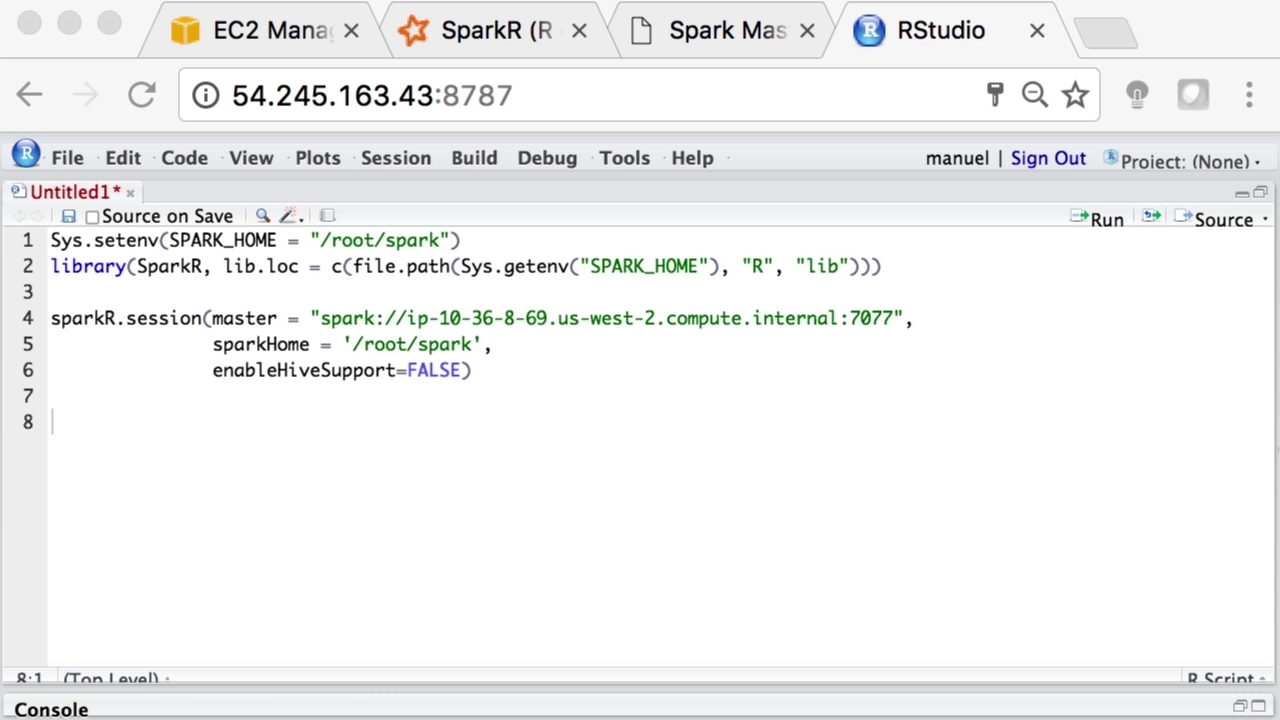 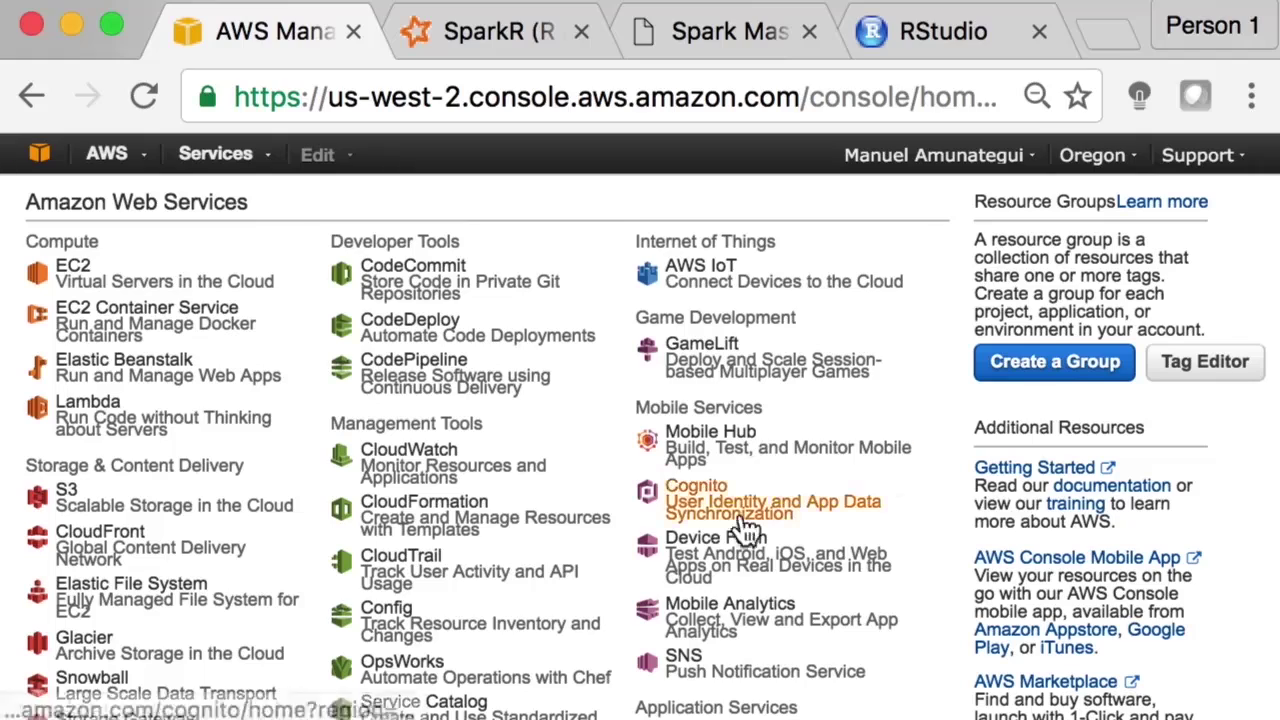  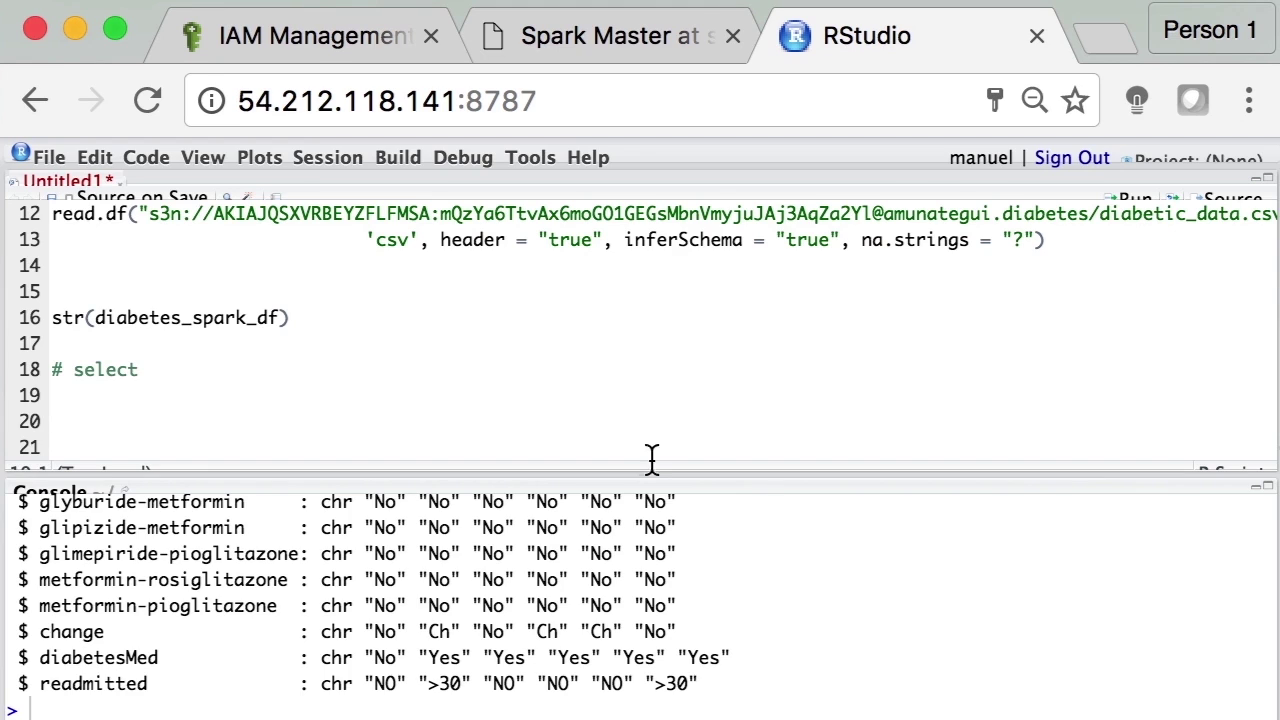            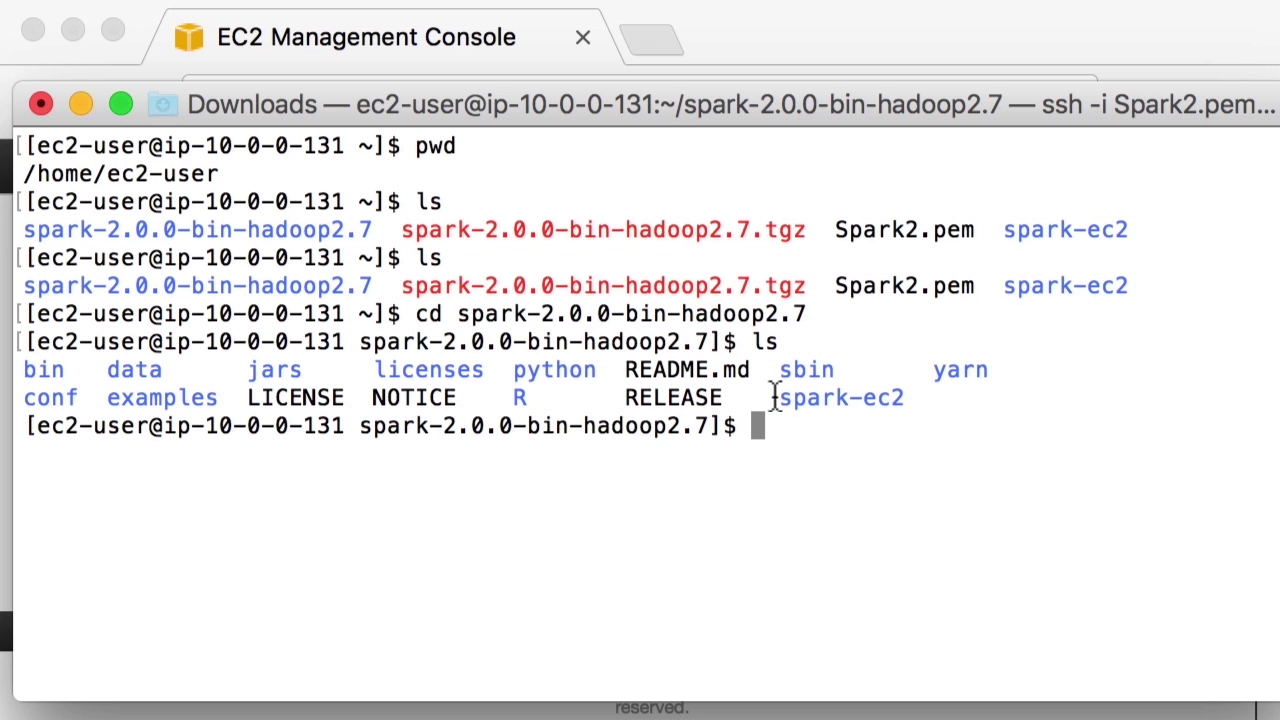 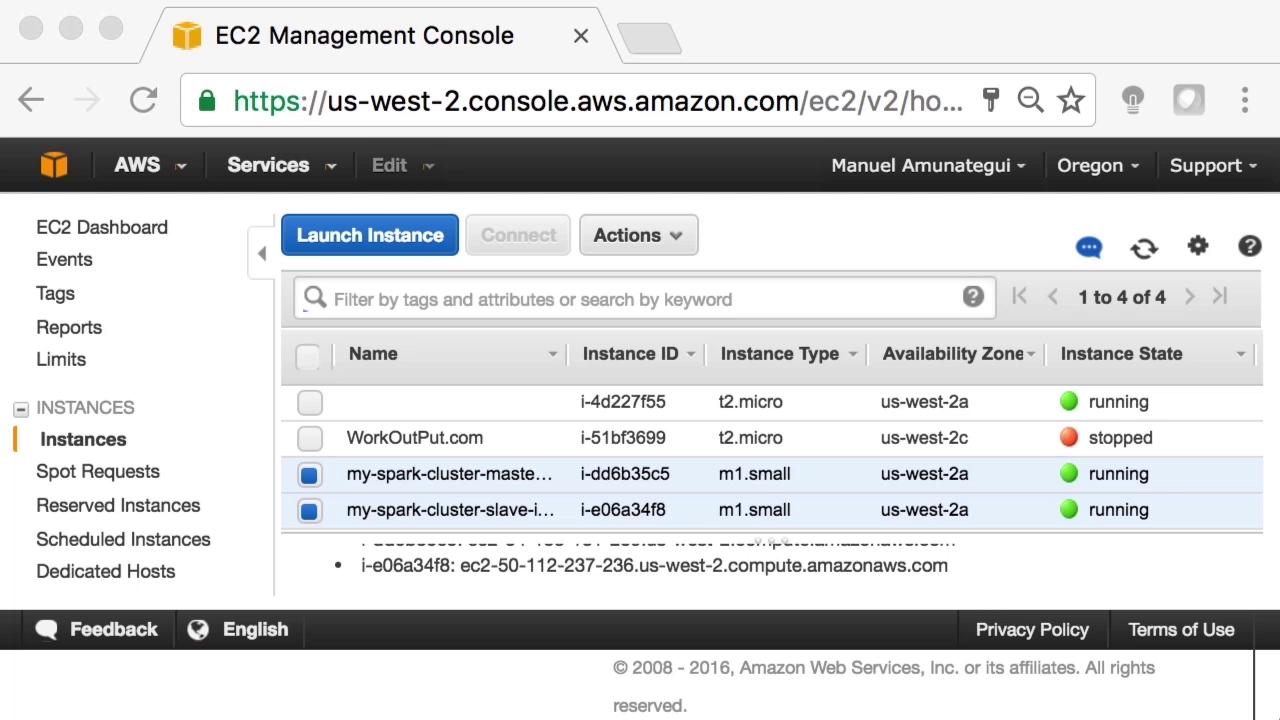 [/spoiler]
Related Torrents
|
|||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||||


Home - Browse Torrents
ExtraTorrent.st is in compliance with copyrights
2025 ExtraTorrent.st